
Cheerio Web Scraping:如何使用 Node.js 抓取静态页面的教程
有兴趣从静态网页收集数据吗?Cheerio 和 Axios 库非常适合这项工作。了解开始网页抓取项目所需的一切。

Node.js 是用于网页抓取的出色运行时。它最出名的是其用于动态网站的强大无头浏览器库。但您也可以从静态网页收集数据并清理以供进一步使用。一个非常流行的 Node.js 库是 Cheerio。
在本指南中,您将了解什么是使用 Cheerio 进行网页抓取,以及它可以为您的网页抓取项目带来哪些优势。我们还将解释成功从静态网页收集数据所需的其他工具,以及如何使用 Cheerio 和 Axios 构建网页抓取工具。所有信息都将包含在一个真实的示例中,以便您可以练习您的技能。
什么是使用 Cheerio 进行网页抓取?
使用 Cheerio 进行网页抓取涉及多个步骤。
Cheerio 不是一个独立的库:它只能解析或构建网页内容。您首先需要选择一个 HTTP 客户端,例如 Axios,来获取目标网页的 HTML 代码。
获取 HTML 内容后,即可将其加载到 Cheerio 中。然后,该库允许您使用 jQuery 语法来遍历和操作 HTML 结构。Cheerio 允许您使用 CSS 选择器选择页面元素并提取数据,这些数据可以是文本、链接、图像或任何其他信息。您还可以根据属性或值筛选元素。
有些网站需要你处理分页或抓取嵌套在 JavaScript 中的数据。Cheerio 无法执行 JavaScript;如果遇到这种情况,你需要像Playwright 或 Puppeteer这样的无头浏览器库。
使用 Cheerio 进行网页抓取的优势
如果您熟悉 jQuery,那么使用 Cheerio 进行网页抓取非常简单,因为它具有类似的语法。
Cheerio 是一款非常灵活的工具。它基于 parse5(用于解析 HTML)和 htmlparser2(用于解析 XML 文档)构建而成。它结合了两者的功能;例如,parse5 确保符合 HTML 标准。实际上,它可以解析任何 HTML 和 XML 文档。此外,该库还允许您遍历 DOM 结构,以便您可以选择和操作特定元素。
它还支持一系列 CSS 选择器,因此您可以轻松地定位文档中的元素。
与大多数解析库一样,Cheerio 占用的资源很少。该工具在服务器端运行,不需要完整的浏览器环境,因此您可以处理复杂的页面。
使用 Node.js 库 Axios 和 Cheerio 抓取静态页面
在本分步教程中,我们将从 books.toscrape.com 抓取书籍列表(书名、价格、评分、库存和 URL)。尽管 Node.js 有一个集成的请求库,但它并不易于使用,因此很少有人选择它来获取数据。因此,我们将使用 Axios 来获取页面。

硬件需求
- Node.js。 确保你的系统上安装了最新的 Node.js 版本。你可以从 官方网站.
- Axios。 您可以通过运行来添加它 npm 安装 axios 在您的操作系统终端中。
- 啦啦队。 您可以通过运行来添加它 npm 安装 Cheerio.
导入库
步骤 1.首先,让我们导入必要的库
1)导入Node.js HTTP 客户端 axios。
import axios from 'axios'
2)导入Node.js解析器Cheerio。
import { load } from 'cheerio'
3)导入内置的Node.js文件系统模块,将结果写入CSV文件。
import fs from 'fs'
下载页面
第一步:下载目标页面。
const start_url = "http://books.toscrape.com/"
步骤 2.创建一个列表来存储数据。
const books_list = []
步骤 3.定义scrape()函数。
async function scrape(url) {
步骤 4.发出 HTTP 请求并等待响应。
let resp = await axios.get(url)
步骤 5.从响应中提取 HTML。
let resp_html = resp.data
提取数据点
步骤 1.将 HTML 加载到 Cheerio $对象中。
const $ = load(resp_html)
步骤 2.将 Cheerio 实例传递给parse()函数。
parse($)
步骤 3.找到下一页选择器和href属性以抓取下一页。
					try {
        let next_href = $('.next > a').attr("href")
// In case the '/catalogue/' part of the URL is not found within
// the href attribute value, add it to the href
if (!next_href.includes('catalogue')){
next_href = `catalogue/${next_href}`
}
步骤 4.格式化我们要抓取的下一个页面的绝对 URL。
					let next_url = start_url + next_href
console.log('Scrape: ' + next_url)
步骤 5.再次调用scrape()函数并传递 URL。
const book_price = $(element).find('.price_color').text().replace('£', '')
解析 HTML
步骤 1.定义解析函数。
function parse($){
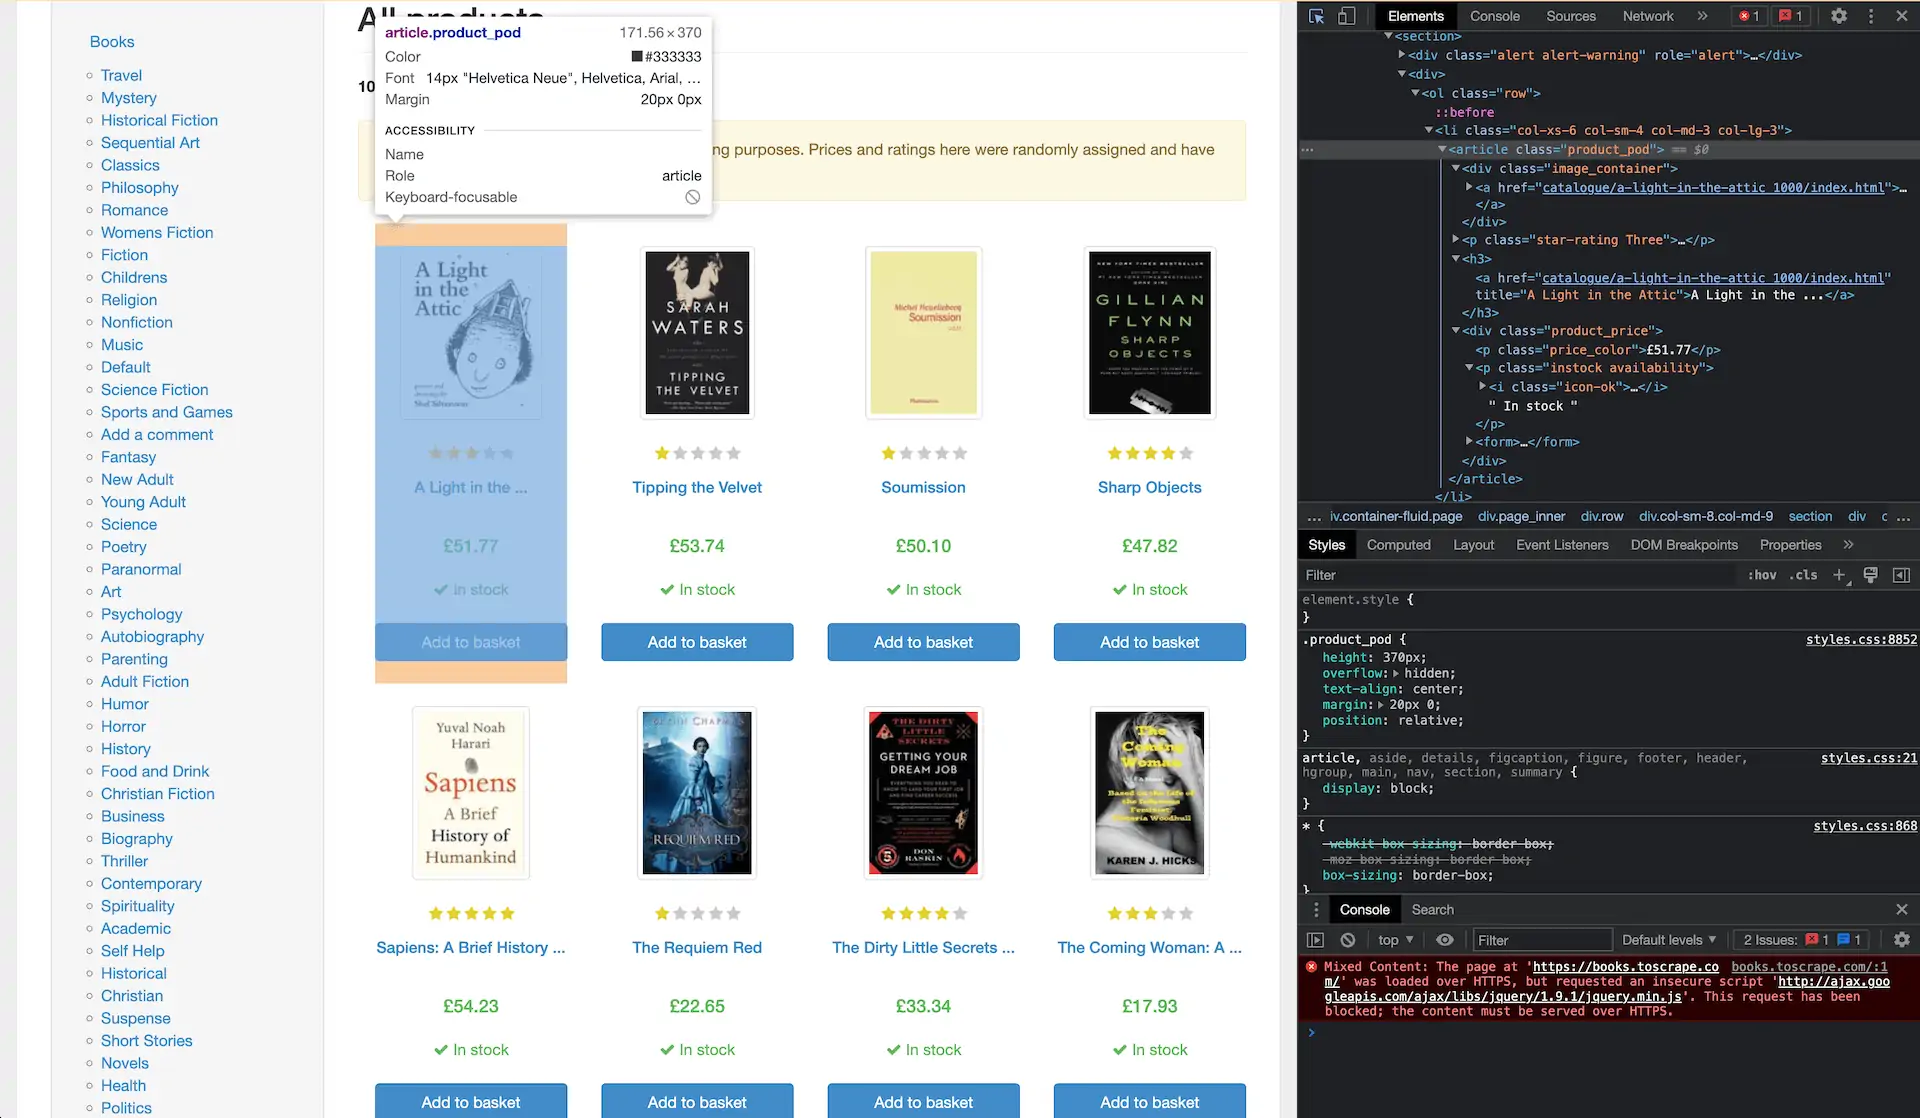
步骤 2.现在,我们需要确定数据点的位置。我们来抓取四个元素:书名、价格、评分和库存情况。右键单击页面上的任意位置,然后选择“检查”。您可以看到它们都属于一个名为product_pod 的类:
步骤 3.我们可以提取整个类:
$('.product_pod').map((i, element) => {

但是得到的数据会比较混乱,所以还是具体一点吧。
1)通过查找元素内的 H3 标签来提取书名。
const book_title = $(element).find('h3').text()
2)然后,通过去掉英镑符号来提取书价。
const book_price = $(element).find('.price_color').text().replace('£', '')
3) 现在,从带有`star rating` 和`Num` 类的`p`标签中获取书籍评分(即书籍的评分)。这部分稍微复杂一些,因为评分包含在包含两个单词的书名中,而我们只需要其中一个。
首先,你需要找到具有该类名的元素,并获取该类名属性的值,该值会返回一个字符串。你可以使用空格作为分隔符将该字符串拆分成单词列表,然后提取第二个单词。
					const book_rating = $(element).find('p.star-rating').attr("class")
.split(' ')[1]
4) 通过查找instock类的元素并删除不必要的空格来提取图书库存信息。
const book_stock = $(element).find('.instock').text().trim()
5) 通过查找product_pod元素中的a标签并获取其href属性来获取书籍 URL ,你需要将其附加到start_url。
const book_url = start_url + $(element).find('a').attr("href")
第四步,现在,让我们把数据点添加到列表中:
					books_list.push({
    "title": book_title,
    "price": book_price,
    "rating": book_rating,
    "stock": book_stock,
    "url": book_url
})
步骤 5.结束迭代。
					})
    //console.log(books)
}
将输出保存到 CSV 文件
步骤 1.现在,让我们将所有数据写入 CSV 文件,以构建数据结构。
function write_to_csv(){
步骤 2.从 books 对象中获取键值,这将成为 csv 文件的第一行。
var csv = Object.keys(books_list[0]).join(', ') + '\n'
步骤 3.遍历书籍字典中的每个元素。
books_list.forEach(function(book) {
步骤 4.在csv变量中添加新行,并在末尾添加换行符。
					csv += `"${book['title']}", ${book['price']}, ${book['rating']}, ${book['stock']}, ${book['url']},\n`
})
//console.log(csv)
步骤 5.将输出写入 CSV 文件。
					fs.writeFile('output.csv', csv, (err) => {
        if (err)
            console.log(err)
        else {
            console.log("Output written successfully")
        }
    })
}
步骤 6.然后,将 URL 传递给抓取函数,并告诉 Node.js 等待所有抓取操作完成,然后再继续写入输出。
await scrape(start_url)
步骤 7.调用函数写入输出。
write_to_csv()
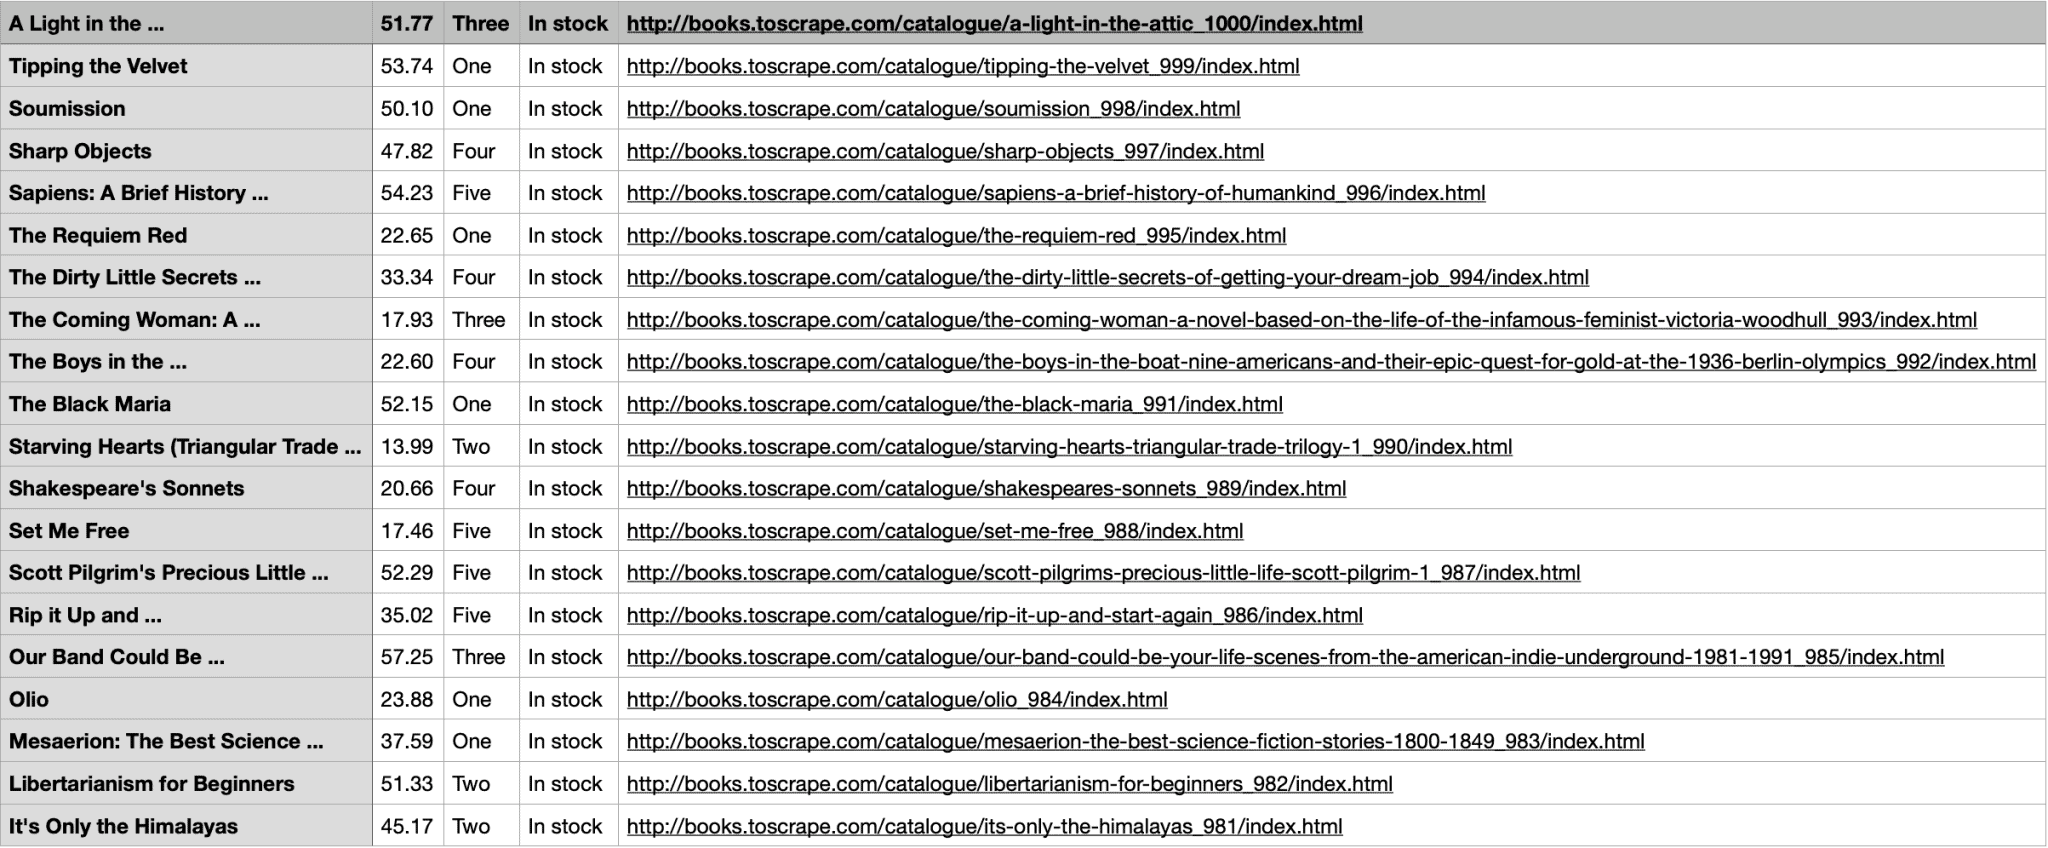
这是完整的代码:
					import axios from 'axios'
import { load } from 'cheerio'

// For writing into the output file
import fs from 'fs'

const start_url = "http://books.toscrape.com/"

const books_list = []

    // Requesting the page with the help of Axios and waiting for the response
    let resp = await axios.get(url)
    let resp_html = resp.data
    // Loading the html into Cheerio. $ - Cheerio object
    const $ = load(resp_html)
    // Passing the Cheerio instance to the parse() function
    parse($)

    try {
        // Try finding the  next page selector and
        // extract the href attribute for scraping the next page
        let next_href = $('.next > a').attr("href")
        // In case the '/catalogue/' part of the URL is not found within
        // the href attribute value, add it to the href
        if (!next_href.includes('catalogue')){
            next_href = `catalogue/${next_href}`
        }
        // Formatting the absolute URL of the next page we are going to scrape
        let next_url = start_url + next_href
        console.log('Scrape: ' + next_url)
        // Calling the scrape() function again and passing it the URL
        await scrape(next_url)

    } catch {
        // Next page selector not found, end job
        return
    }

}

// Function for parsing the html of the page.
function parse($){
    // The selector for each distinct book element on the page is an article
    // tag with the class of "product_pod". This line finds all such elements
    // and begins iterating through them.
    $('.product_pod').map((i, element) => {
        // To get the title, we find the h3 tag within the element and
        // extract its text.
        const book_title = $(element).find('h3').text()
        // Price is also simple, we just get rid of the pound sign
        const book_price = $(element).find('.price_color').text().replace('£', '')
        // The book ratings are easily scraped from the p tag with the classes
        // "star rating" and "Num" where "Num" is the rating the book has
        // received. To extract the rating, we first find the element with that
        // class, get the value of the "class" attribute which returns a string:
        // e.g. "star-rating One", split that string by whitespaces and assign
        // the second element of the resulting list to our variable.
        const book_rating = $(element).find('p.star-rating').attr("class")
            .split(' ')[1]
        // Simply finding the element by the "instock" class, extracting the
        // text and trimming the resulting string to strip away unnecessary
        // whitespaces.
        const book_stock = $(element).find('.instock').text().trim()
        // To extract the url of the book, we find the a tag within the
        // product_pod element and get its "href" attribute which we append to
        // the start_url
        const book_url = start_url + $(element).find('a').attr("href")
        // Appending the results dictionary to the books_list
        books_list.push({
            "title": book_title,
            "price": book_price,
            "rating": book_rating,
            "stock": book_stock,
            "url": book_url
        })
    })
    //console.log(books)
}

function write_to_csv(){
    // Getting the keys from the books object, this will become the first line of the csv file
    var csv = Object.keys(books_list[0]).join(', ') + '\n'
    // Iterating through each book dictionary element
    books_list.forEach(function(book) {
        // Adding a new line to the csv variable with the line break at the end
        csv += `"${book['title']}", ${book['price']}, ${book['rating']}, ${book['stock']}, ${book['url']},\n`
    })
    //console.log(csv)
    // Writing the output to a output.csv file
    fs.writeFile('output.csv', csv, (err) => {
        if (err)
            console.log(err)
        else {
            console.log("Output written successfully")
        }
    })
}

// Script starts here, we pass the URL we are going to start our scrape on to
// the scrape function and tell node for it to be awaited so that all of the
// scrapes finish before we move on to writing the output
await scrape(start_url)
// Calling the function to write the output
write_to_csv()
使用 Node.js 和 Puppeteer 抓取动态网页
如果您想抓取动态页面,我们还准备了一份使用无头 Node.js 浏览器库 Puppeteer 的分步教程。该指南将引导您从 quotes.toscrape.com 提取数据,特别是文本、引用、作者和标签数据点。我们还将向您展示如何处理延迟渲染,以及如何在脚本中集成代理。
这是使用 Node.js 库 Puppeteer 进行网页抓取的分步指南。
